Characters to avoid in file and folder names
File names affect URLs, compatibility between systems and how efficiently you work. A small detail that prevents many problems.
Read the articleAlmost all of us use Ctrl + F (or Cmd + F on a Mac) to find a word quickly in a document or on a web page. It is simple, fast and familiar. The problem starts when you work with thousands of documents.
Almost all of us use Ctrl + F (or Cmd + F on a Mac) to find a word quickly in a document or on a web page. It is simple, fast and familiar. The problem is that the moment you work with thousands of documents, databases, logs or complex source code, Ctrl + F is no longer enough.
In the age of massive data we need something far smarter: advanced search engines such as dtSearch, competing tools and regular expressions (regex). These do not just find a word. They can identify patterns in text, search across dozens of file types and work at terabyte scale.
Ctrl + F works acceptably when:
But the list of limitations is much longer:
If we had to compare, Ctrl + F is a small torch: it helps in your own room, but you will never light up a whole building with it.
dtSearch is one of the best-known search engines for enterprise environments, used heavily in:
("fraud" OR "evasion") AND "financial report" w/10 "Q4"
This finds documents where “fraud” or “evasion” appears within ten words of “financial report” and “Q4”.In practice, dtSearch gives you a view of your entire universe of files, not just of the one document open in front of you.
Regular expressions (regex) are a language for describing patterns in text. Combining regex with an advanced search engine (dtSearch, Elasticsearch, grep/ripgrep and so on) gives you a power Ctrl + F will never have.
E-mail addresses:
[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}
Dates (MM/DD/YYYY format):
(0[1-9]|1[0-2])/(0[1-9]|[12][0-9]|3[01])/\d{4}
Error messages in logs:
ERROR\s+\d{3}:\s+.*
Modern search tools such as dtSearch, Elasticsearch or ripgrep can run such expressions across thousands or millions of files, saving hours or even days of manual work.
dtSearch is not the only player on the market. Depending on your needs, you can combine or choose other solutions:
Elasticsearch is a distributed search and analytics engine, ideal for:
X1 Search is strongly oriented towards:
Copernic Desktop Search is a lighter solution, good for:
ripgrep and the classic grep utility are hugely popular among developers thanks to:
Each tool has its strengths, but they all have one thing in common: they go far beyond the simple functionality of Ctrl + F.
When you find the right information in seconds rather than hours, decisions are taken faster and projects move more smoothly.
Advanced search (dtSearch, regex, Elasticsearch) reduces human error: you no longer skip relevant documents just because you did not guess the exact word.
In the legal, financial or medical fields, finding information quickly and completely can be the difference between compliance and sanctions. Enterprise search engines are indispensable in these scenarios.
Analysing logs with regex and search engines makes it possible to detect suspicious patterns, recurring errors or intrusions.
Organisations that can search their own resources efficiently become more agile, reduce duplicated work and increase the value of their internal knowledge.
If you work with:
then Ctrl + F is no longer enough. You need tools such as dtSearch, engines such as Elasticsearch, powerful desktop solutions (X1, Copernic) and regex as a language for describing patterns.
Moving from simple search to advanced search is not just a technical upgrade. It is a strategic step for anyone who wants to get the most out of the data they hold.
All of these concepts (dtSearch, regex, enterprise search engines) are extremely powerful, but also technical enough to become discouraging for someone who simply wants fast and correct results, not yet another complicated skill to learn. Instead of spending dozens of hours on syntax, advanced options and edge cases, it is far more efficient to work with a team that already masters these tools and uses them daily in real projects.
We take care of the complex part: designing the indexing, defining the regex patterns, choosing the right search engine, tuning performance. You get performance, precision and time saved. Instead of adding another “language” to your agenda, you work with us and obtain the same benefits, or greater ones, in a way that is simpler, more predictable and scalable for your business.
The first step is the archive assessment: a clear report on what you have, what can be processed, how long it takes and with what risks.
Request an archive assessment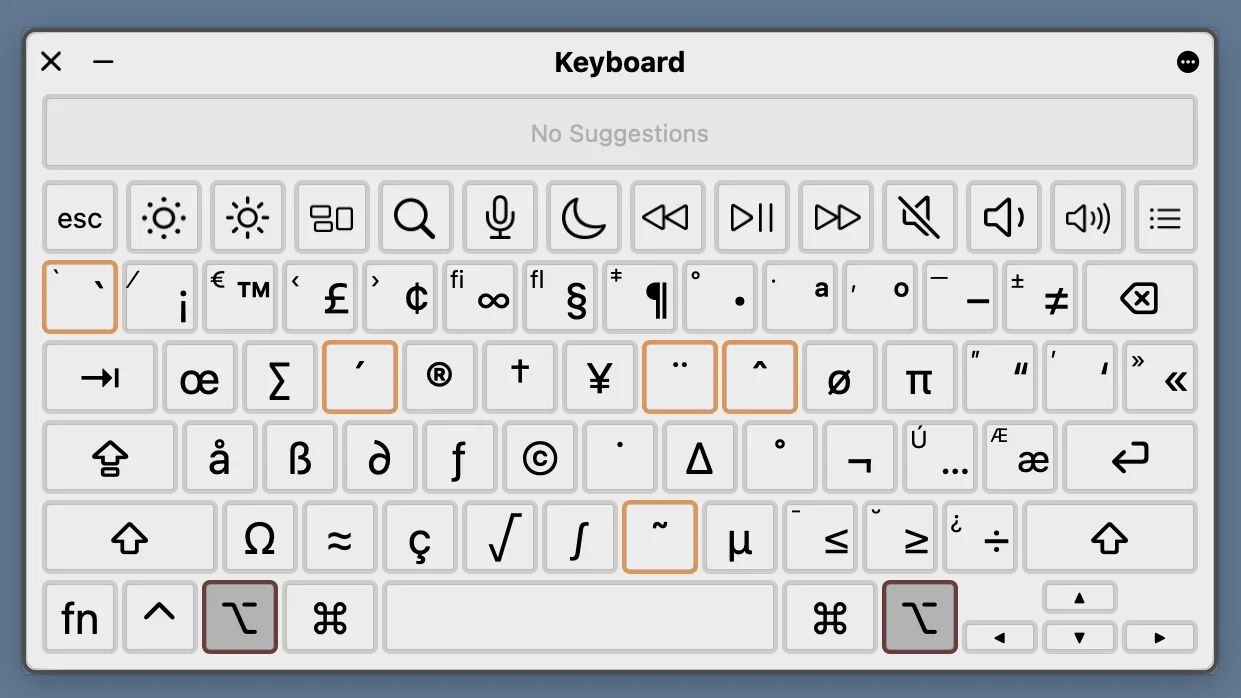
File names affect URLs, compatibility between systems and how efficiently you work. A small detail that prevents many problems.
Read the article
In an increasingly digital legal world, law firms face ever larger volumes of documents. Processing them intelligently, with OCR, AI and machine learning, is becoming a priority for efficiency and competitiveness in 2026.
Read the article
As organizations continue moving toward digital transformation, one question consistently comes up: Is a digital document archive better than a physical, paper-based archive?
Read the article